The ranking is fine. The traffic isn't.
Enterprise SEO teams spent two decades chasing one promise: rank on the first page and the visits follow. That deal is quietly breaking. A page can hold the top position in Google for months and still lose a third of its organic traffic, with no competitor outranking it. The cause sits above the blue link. Google writes an answer first, and for a growing share of queries there is no reason left to click through.
Answer engine optimization, or AEO, is the work of making a company's content the material those systems quote instead of the material they summarize around. It borrows habits from SEO but rewards different behaviour. Classic SEO fights for a position on a page of results. AEO fights for a sentence inside a generated answer.
What changed in the search transaction
Search used to flow in one direction. Someone typed a query, scanned ten links, picked one, and the site recorded a visit. Ranking well was the whole job, and the visit was how you knew it had worked.
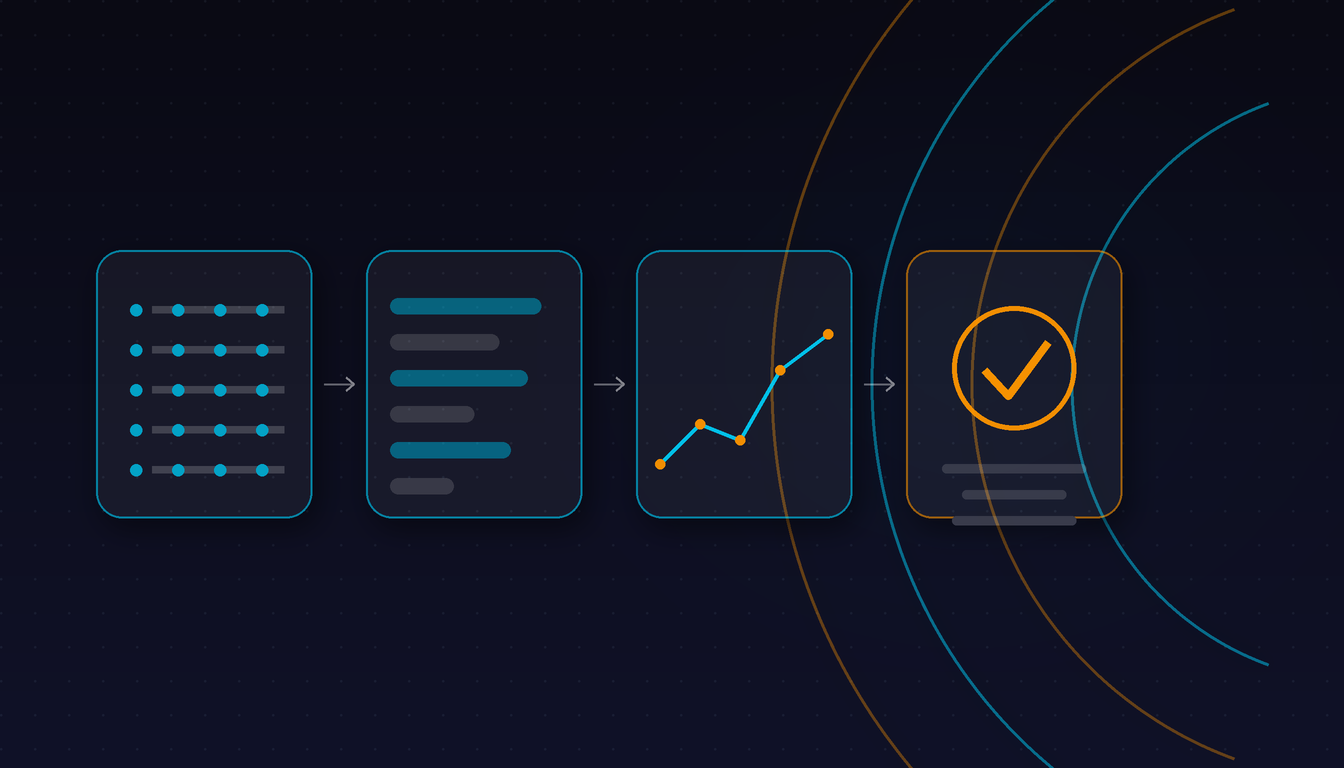
The answer engine now does the scanning. ChatGPT, Perplexity, Gemini and Google's AI Overviews read across dozens of pages, synthesize a response, and cite a short list of sources. The reader often never leaves the interface. When they do leave, they arrive further down the funnel: already informed, already narrowing options, holding a shortlist that formed without anyone visiting a website.
Traffic volume and business value have decoupled. A fall in sessions is not automatically a fall in demand. It can mean the demand is being qualified somewhere the analytics package cannot see.
The numbers that reframe the problem
Seer Interactive's September 2025 study measured organic click-through rate falling 61 percent on queries where an AI Overview appeared, from 1.76 percent to 0.61 percent. Paid click-through fell 68 percent over the same window. The same analysis found brands cited inside those overviews earned 35 percent more organic clicks and 91 percent more paid clicks, which is the first sign that the new game still has winners.
A randomized field experiment posted to SSRN in April 2026 put firmer numbers on the shift. When an AI Overview was shown, outbound clicks to publishers fell 39.8 percent and zero-click searches rose 34.5 percent. That is causal evidence from a controlled trial, not a dashboard correlation.
Conductor's 2026 AEO and GEO benchmarks, drawn from 3.3 billion sessions across 1,215 enterprise domains, found that AI referral traffic accounts for 1.08 percent of total website traffic across ten key industries. IT sites led at 2.80 percent. Octane11's B2B research reached a similar floor from another direction: AI search still drives under 2 percent of B2B search referrals, but it grows faster than every other channel, and the mix inside it is moving. ChatGPT held roughly 72 percent of AI referrals in February 2026, down from an 86 percent peak in October 2025, while Gemini climbed from 4.5 percent to 13 percent of that same pool.
Those small percentages invite complacency. They should not. HubSpot's 2026 State of Marketing found 49 percent of marketers had already watched search traffic fall because of AI answers, and 58 percent described the AI referral traffic they did receive as high intent.
Why the smaller channel converts harder
Seer Interactive measured LLM visitors converting at 15.9 percent from ChatGPT, 10.5 percent from Perplexity and 5 percent from Claude, against a 1.76 percent organic search baseline. Ahrefs found AI search visitors produced 12.1 percent of sign-ups while making up 0.5 percent of visitors, a ratio near 24 to 1 against organic traffic.
The reason these visitors convert is intent. A person who asks an assistant which ERP integrator handles multi-entity inventory in Canada has already done the framing work. They are not browsing. They are choosing. Losing visibility at that moment costs far more than the session volume suggests, because the sessions being lost were the ones that would have converted.
What earns a citation
There is no ranking table for AI answers, which makes AEO feel unpredictable. The retrieval mechanics are less mysterious than they look. Systems favour content they can parse cleanly, extract whole, and verify as current and tied to an identifiable source.
Structure for extraction, not for prose
Language models pull at the paragraph level. A paragraph carrying two ideas tends to get cut, because the model cannot isolate the half that matches the query. A paragraph with one idea in two to four sentences can be lifted whole and quoted. The practical rule: if a paragraph leans on "but", "however" or "meanwhile" to do real work, split it into two paragraphs.
Answer first, explain after
Put the direct answer in the first sentence of a section, then support it. Retrieval tends to weight the opening lines when deciding whether a passage is worth citing. SE Ranking's analysis of ChatGPT citations found that sections of 120 to 180 words between headings pull roughly 70 percent more citations than sections under 50 words. Articles over 2,900 words averaged 5.1 citations, against 3.2 for pieces under 800 words.
Schema helps machines understand, not machines cite
Structured data clarifies who wrote a page, what organisation stands behind it, and when it was published. That context matters for entity resolution, and it is worth doing. What schema does not do is reliably lift citation frequency on its own. SE Ranking found pages with FAQ schema averaged 3.6 citations while pages without it averaged 4.2. Use Article, FAQ and Organization schema to remove ambiguity, not as a citation lever.
Freshness and entity consistency
Perplexity weights recency roughly 3.3 times more heavily than Google does, and only about 11 percent of the domains cited by ChatGPT and Perplexity overlap. One optimisation pass does not cover both engines, so treat them as separate targets. Keeping publication and review dates accurate, and describing the company the same way across its site, profiles and directories, does more than any keyword density target.
The llms.txt file is not the lever it is advertised as
The /llms.txt proposal gets breathless coverage. In practice it is a voluntary crawl-intent declaration, and no major platform has confirmed it as a ranking or citation input. Add it because it helps agents read a site cleanly. Do not expect it to move citation counts.
Where enterprises go wrong
The most common mistake is treating AEO as a content-volume problem. Teams publish more pages, each thinly differentiated, and watch none of them get cited. Models reward distinct claims and original data, not word count. A hundred pages that restate a competitor's framework are worth less than one page that publishes a number nobody else has.
A second mistake is measurement. Dashboards still report sessions, rankings and bounce rate. Zero-click answers produce no session to measure, so the channel looks empty even when it is steering decisions. The commercially valuable moment, when an assistant recommends a vendor onto a shortlist, happens before any trackable touchpoint. Teams that only instrument the click will keep concluding the channel does not work.
A third mistake is technical. Sites that render core content only after a heavy JavaScript pass, block crawlers, or hide specifications behind interactive widgets are handing retrieval to competitors whose content is easier to read. For an enterprise platform with a decade of accumulated front-end debt, this is often the highest-leverage fix available, and it is invisible on a rankings report.
A practical AEO plan
Baseline before optimising
Ask the major assistants the twenty questions a buyer would actually ask, log which brands and pages get cited, and repeat the exercise monthly. Without a baseline there is no way to separate improvement from noise.
Fix the pages that carry commercial intent
Prioritise pricing, comparison, category and specification pages over blog posts. Those are the pages an assistant reaches for when a purchase decision is close.
Build content competitors cannot copy
Original research, proprietary benchmark data, internal cost analyses and first-party product facts give an assistant no alternative source. Anything summarised from public pages is disposable, because the model can summarise it from anywhere.
Measure share of answer, not just rank
Track citation frequency, how often the brand is named without a link, and which sources receive credit. Pair that with the intent quality of the traffic that does arrive. A small, well-targeted AI referral stream can outperform a large generic one, and the two require different follow-up.
What this means for e-commerce and service sites
For online stores the exposure is direct. Product queries increasingly resolve inside an assistant, which returns a recommendation and a price without a click. Retailers that publish structured, accurate product data and clear comparison content give themselves a chance to be that recommendation. Those relying on a paid ranking alone are being quietly disintermediated, and the loss shows up as a slow decline in branded search rather than a cliff.
For service businesses the shift is subtler and arguably more valuable. A generated answer that names a firm as a credible provider is a referral that arrives pre-qualified, with the credibility of the assistant behind it. The work is to make the firm legible: consistent naming, verifiable credentials, specific case evidence, and pages an assistant can quote without rewriting them first. On a technical level that means clean HTML, honest dates and content that states what the firm does in the first sentence of every page.
The takeaway
Search never disappeared. It moved into a layer where the answer arrives before any link, and it rewards different signals than the ranking era did. Enterprises that treat AEO as a measurement and content-discipline problem will keep showing up where buyers are deciding. Waiting for that traffic to come back on its own no longer works, because the behaviour that produced it has already changed.