The microservices default is losing its grip
For most of the last decade, telling an architecture review that you were breaking up the monolith was the fastest way to make the room nod. Microservices were the grown-up choice. A monolith was what you had before you knew better. That consensus is coming apart in 2026, and not because the original reasoning was wrong.
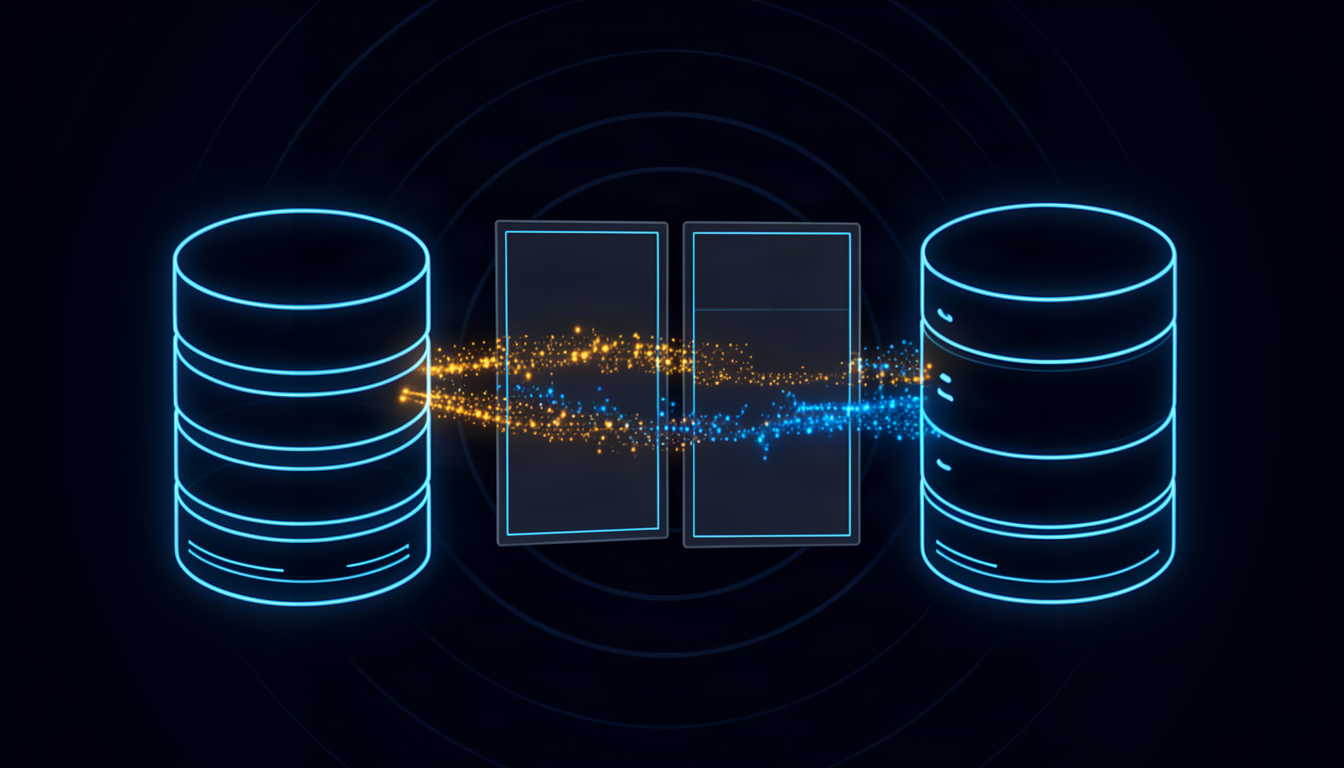
The pattern is documented well enough now to name it. Organizations split systems into dozens of services, hired platform engineers to run them, and then watched delivery slow down. Features took longer to ship, incident calls ran longer, and the cloud bill kept climbing. For a meaningful share of those teams the direction of travel now runs the other way. They are merging services back into a single deployable unit with hard internal boundaries. The result has a name: the modular monolith.
Call it a correction rather than a reversal. Complexity has a carrying cost, and plenty of enterprises bought complexity they never needed and could not staff.
What a modular monolith actually is
Simon Brown coined the term in 2015, and it has been quietly gaining ground ever since. The idea fits in one line: one deployable artifact, many well-separated modules, enforced boundaries between them.
That last part is what separates it from the tangle people mean when they say "monolith." A traditional monolith is a codebase where any class can call any other class, where billing logic reaches straight into shipping tables, and where nobody can tell you where a business rule lives without opening three files. A modular monolith keeps the single deployment but draws firm lines inside it.
Five properties that do the work
- Explicit module boundaries. Each business domain gets its own namespace or package. Nothing is shared by accident.
- Unidirectional dependencies. Modules call each other through published interfaces only. Cyclic dependencies are treated as defects and fail the build.
- Hidden internals. A module's internal classes and tables are off-limits to everyone else. Access control is enforced by the compiler or the language, not by a wiki page nobody reads.
- Event-first communication. Modules publish domain events instead of reaching into each other synchronously, which keeps coupling low without adding a network hop.
- Architecture fitness functions. Automated checks in continuous integration verify the boundaries on every commit.
If that list looks like the discipline you would apply to microservices, that is the point. You keep the rigor and drop the distributed systems tax.
The numbers behind the reversal
The evidence stopped being anecdotal a while ago. A 2024 multivocal literature review published in MDPI's Electronics catalogued four well-documented cases of teams switching back from microservices to a monolith: the Istio control plane, Amazon Prime Video's video monitoring service, Segment, and InVision. The authors found the same five reasons recurring across all four: cost, complexity, scalability, performance, and organization.
Amazon's case is the most cited for good reason. The Prime Video team moved a video quality monitoring service from a distributed design back to a single process and reported a cost reduction of over 90 percent, because the work could happen in memory instead of passing video frames through an S3 bucket and a chain of step functions. They ended up with better scaling behavior than the distributed version they replaced.
Survey data tracks the same direction. Reporting on CNCF survey results puts the share of organizations that consolidated at least some microservices into larger deployable units at roughly 42 percent in early 2026, up from about 23 percent in 2024. Agreement with the statement that microservices are overkill for teams of ten or fewer moved from 61 percent to 84 percent over the same window.
Tooling has matured to the point where the pattern is practical rather than aspirational. Spring Modulith shipped its 2.0 release in November 2025 and 2.1 in June 2026, and it now enforces module boundaries and generates documentation from the dependency graph. ArchUnit's freezing rule is the more interesting one for anyone with existing code: it records the current set of boundary violations as a baseline and fails the build only when new ones appear, so a team can turn architecture rules on today instead of after a six-month cleanup. Shopify runs its commerce platform on this model, one Rails codebase with domain components and Packwerk checks in CI to keep the interfaces honest. During the 2025 Black Friday period that platform peaked at 489 million requests per minute and served 90 petabytes of data. A single deployable is not a scaling ceiling.
The cost nobody budgeted for
Microservices solve a real problem. They let many autonomous teams ship independently on a large, stable domain. That is a valuable property, and when you have the organization to match, it pays for itself.
What got lost is that the benefit scales with team count, while the cost arrives immediately. A ten-person team that splits into twelve services pays the full price of distributed systems on day one and collects almost none of the autonomy dividend.
The bill shows up in places that never make it onto a slide. Every service boundary is a network call that can fail, time out, or return stale data. Debugging a slow checkout now means correlating traces across six systems instead of stepping through one stack. Eventual consistency moves bugs from "this is wrong right now" to "this is wrong for the next four seconds, maybe." Add a service mesh, an API gateway, per-service CI pipelines, and a monitoring stack for each, and an application that could run on one well-provisioned database ends up needing a small platform team to keep the lights on.
Published infrastructure comparisons for a mid-sized application put a modular monolith in the range of roughly one to twenty-three hundred dollars a month, against four to eight thousand dollars for a comparable deployment of ten to fifteen services. That gap is the compounding kind. It shows up in FinOps reviews, and it is one reason cloud cost optimization keeps landing on the board agenda.
There is an AI angle too. Language models and retrieval pipelines work best against stable, well-defined data boundaries. Handing a model a scattering of services with duplicated entities and inconsistent semantics produces worse output and slower delivery. An architecture chosen for scaling reasons in 2020 now constrains what you can build in 2026.
When microservices still earn their place
None of this means you should refuse to distribute a system. Microservices remain the right answer when several conditions hold at once.
- You have enough autonomous teams that coordination between them is the real bottleneck.
- Parts of the domain have genuinely different scaling or hardware profiles, such as a GPU-bound inference service sitting next to a routine CRUD API.
- Regulatory or isolation requirements force a hard boundary, for example a payment service that has to run inside its own compliance scope.
- The domain has stabilized enough that its boundaries are unlikely to move for a year or more.
If three of those four are false, distribution is a cost you are choosing to pay rather than a problem you are solving. The honest test is whether you can name the specific team that needs independent deployment of the service you want to extract. If you cannot, you are about to add a network hop for no reason.
Consolidating without a rewrite
For teams already deep into a distributed design, the way back is incremental. Nobody needs a big-bang migration back to a monolith, and any consultant who proposes one has not read the postmortems.
Start with ownership, not with call graphs
Before you merge anything, find out who owns each service and which business capability it serves. Services that share an owner and a capability are candidates. Services with separate teams and separate release cadences usually are not, even when the call graph looks tangled.
Tag every service with the business domain it belongs to and the team accountable for it. Anything with one domain, one owner, and a single product manager is a consolidation candidate. Anything with two owners is a political problem to solve before it becomes a technical one.
Merge the chattiest pairs first
Measure inter-service traffic and pick the two services that talk to each other most. If service A calls service B forty times to render a single page, that pair is costing you latency and failure surface for nothing. Pulling those two into one process with an internal interface is usually a contained change, and it produces a visible performance result you can show stakeholders in the first sprint. Early wins buy the political capital you need for the harder merges later.
Make the boundaries enforceable in CI
The classic failure mode of a consolidation project is the slow re-tangling of a codebase that used to have clear lines. Guard against it with automated checks that run on every pull request. A dependency rule that exists only in a design document will be violated within a quarter. A rule that fails the build will hold.
Fitness functions turn architecture into something you can test
Neal Ford and Rebecca Parsons introduced architecture fitness functions in Building Evolutionary Architectures, and this is the piece that makes a modular monolith durable rather than aspirational. A fitness function expresses an architectural rule as an executable test.
In practice that means a small set of rules that live in the repository and run with the rest of your suite:
- No module may depend on another module's internal package.
- The orders module may not import anything from the shipping module.
- Domain modules may not depend on the web framework layer.
- Every database table has exactly one owning module.
The point of writing the rules down as code is that the architecture stops depending on who is still on the team. A boundary that only exists in a diagram survives exactly until the person who drew it leaves. A boundary that fails a build survives the turnover, the reorg, and the deadline crunch that makes everyone want to take the shortcut.
What this changes about planning for the next year
The practical shift for most enterprises is a change in the default. When a new system starts in 2026, the modular monolith should be the assumption and selective extraction should be the exception you have to justify. Start with one deployable, enforce module boundaries inside it from the first commit, and keep each module clean enough that pulling one out later is a refactor rather than a rewrite. That preserves every option worth preserving while deferring the operating cost until you can point at a concrete reason to pay it.
For systems already distributed, the work is a portfolio review rather than a rip and replace. Rank your services by how much they cost in infrastructure, latency, and operational attention, then rank them again by how much independent deployment actually buys you. The services sitting high on cost and low on benefit are your queue. Merge those, leave the rest alone, and stop adding services that a single team cannot justify.
The debate in 2026 is less about monoliths versus microservices than about whether you can articulate why the complexity you are carrying exists. Teams that can answer that question tend to end up with a mix, and a thin mix at that. Teams that cannot tend to end up with a distributed system nobody wants to be on call for.
If you are planning a platform consolidation, a service merge, or a re-architecture and want a second opinion on where the boundaries should fall, Tech Hub Services runs architecture reviews and incremental migration work for enterprise teams. Bring the call graph and the org chart, and we will find the merges worth doing first.